
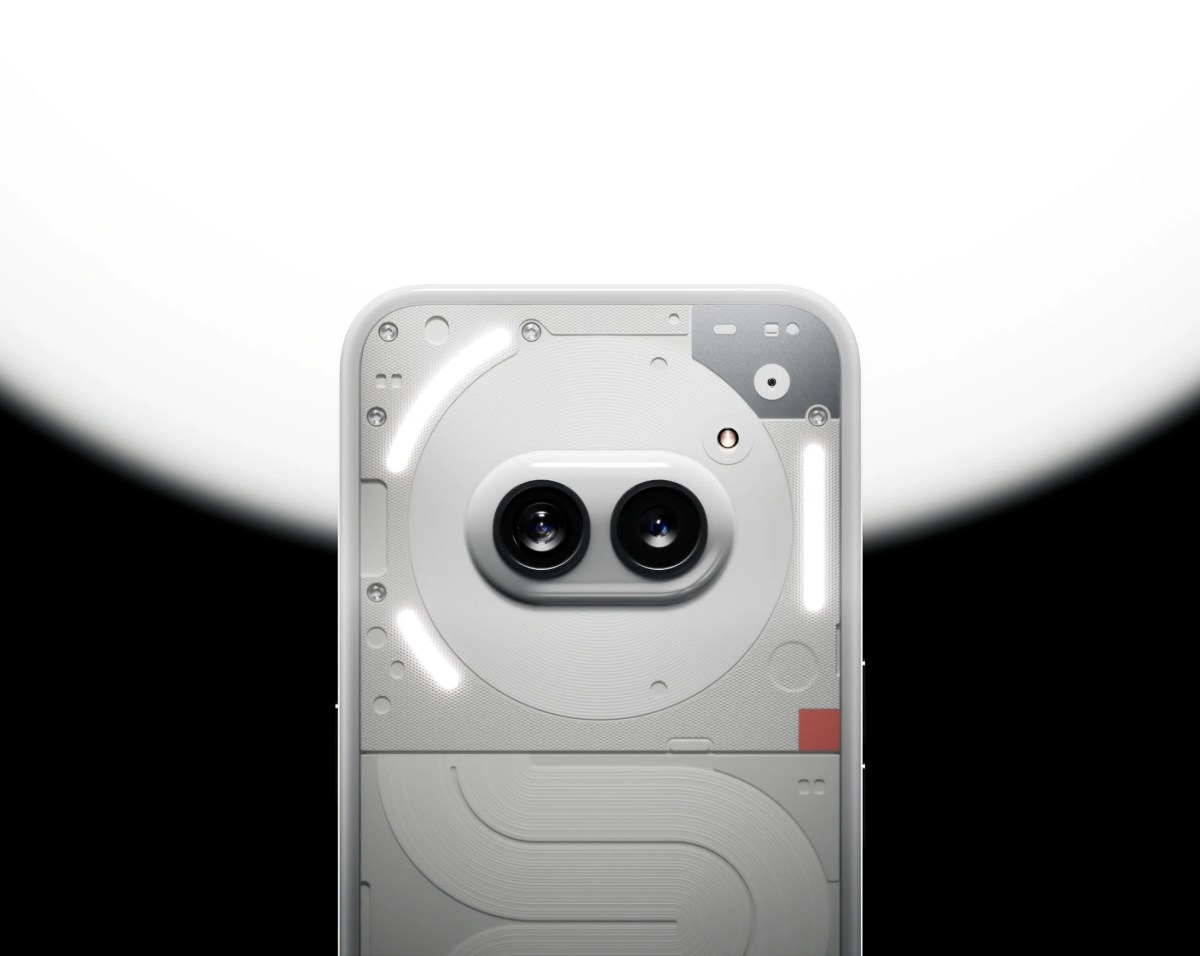
Nothing's AI-First Device Arrives Next Month: What Developers Should Watch
Nothing's CEO says an AI-first device ships next month, but details are scarce. Here is what it could mean for developers building on LLM APIs.
What we actually know, and what we do not
Why hardware makers keep betting on AI
The pitch behind AI-first hardware is usually that general-purpose phones force users through app-by-app workflows, while a dedicated device can route intent directly to a model. For productivity use cases, that could mean drafting, summarizing, scheduling, or retrieving information without tapping through multiple apps.
Whether users want another device for that is an open question. The smartphone already hosts capable assistants, and the bar for a separate gadget is high: it has to do something the phone cannot, or do it noticeably faster. Nothing's design-forward brand may help it get attention, but attention is not the same as daily utility.
What developers should watch for
If Nothing opens any kind of integration surface, the most useful early signals will be the model stack and the access model. Does the device call a single first-party assistant, or does it expose an API that third parties can target? Is inference handled on-device, which affects latency and privacy but limits model size, or in the cloud, which shifts cost and connectivity assumptions?
It is also worth watching how the device handles context. Productivity assistants live or die on whether they can see calendars, messages, and documents. Any developer-facing platform would need a permission model for that data, and the shape of those permissions will determine what kinds of apps are feasible. None of this has been announced, so treat it as a checklist rather than a prediction.
A vendor-neutral takeaway
For teams building with LLM APIs, the practical lesson is to keep the model layer abstracted. Devices like this, if they matter, will likely support more than one backend over time, and the same holds for the assistants and agents you ship. Wrapping provider calls behind a thin internal interface makes it cheaper to swap models when a new device or platform arrives with different constraints on latency, context length, or cost.
It is also a reminder that hardware announcements often precede developer documentation by months. Until Nothing publishes specifics, the responsible move is to note the date and avoid re-architecting around a product whose capabilities are still unconfirmed.
FAQ
Has Nothing revealed what the device is?
Will developers be able to build on it?
Should I change my LLM architecture because of this?
References
Call these models through one gateway
Admesh provides a unified OpenAI-compatible API: one Base URL and one key for Claude, GPT, DeepSeek and more. New accounts get trial credit that never expires.