
Latest
Apple Said to Trim Internal AI Budgets: What It Means for API Teams
Reports say Apple is cutting internal AI spending for engineering teams. Here is what that signals for developers budgeting LLM API usage.
Source: TechCrunchRead article
Engineering blog
Technical notes on the cost, reliability and integration of large-model calls. Based on public documentation from Anthropic and OpenAI, combined with what we learned building our gateway.
Reports say Apple is cutting internal AI spending for engineering teams. Here is what that signals for developers budgeting LLM API usage.
Source: TechCrunchRead article
AI industry PACs reportedly spent millions trying to shape Congress in the midterms with mixed results. Here is what that means for teams building on LLM APIs.
Source: TechCrunchRead article
Qualcomm says it will push harder into AI data centers, leaning on Amazon and Meta partnerships as smartphone sales decline. What it means for API builders.
Source: The VergeRead article
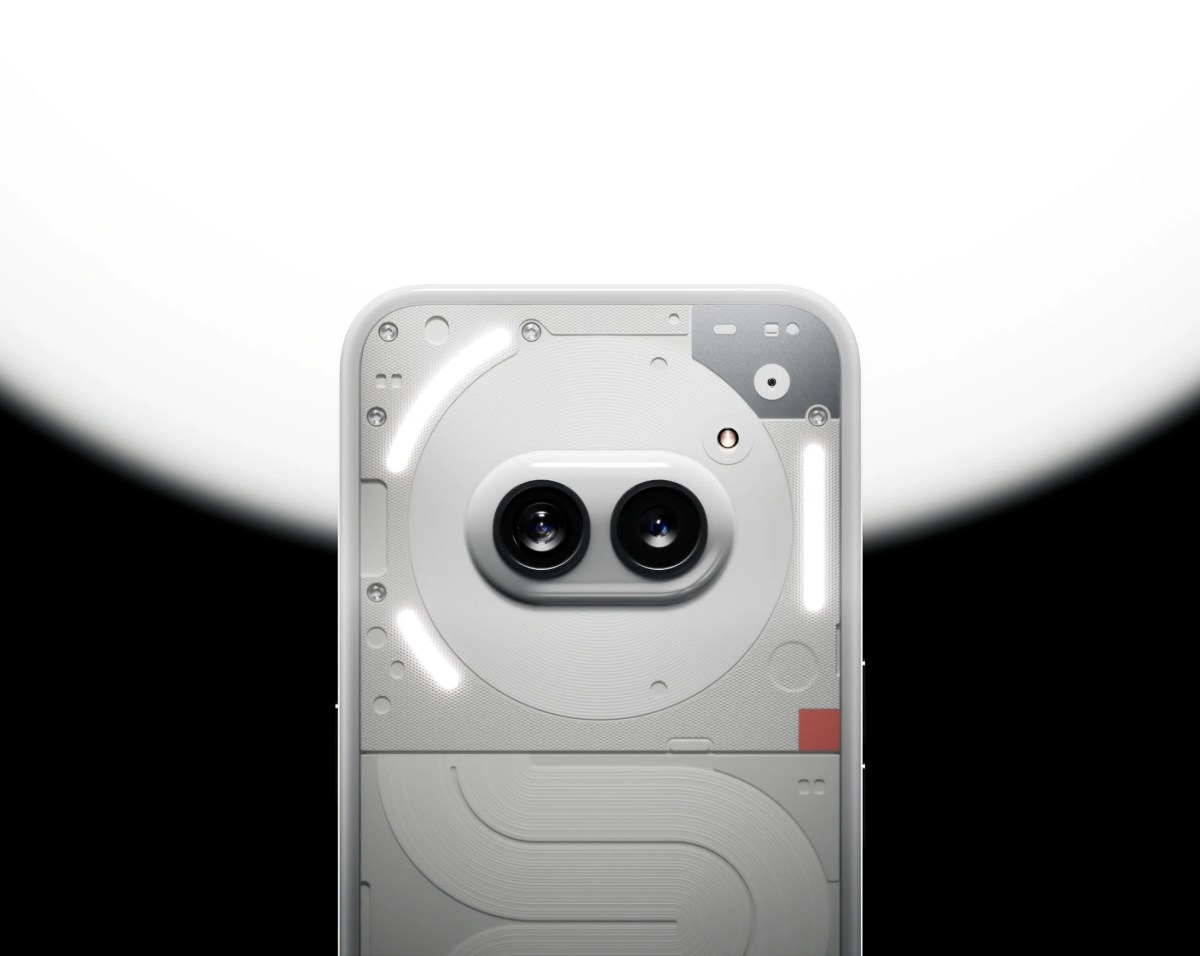
Nothing's CEO says an AI-first device ships next month, but details are scarce. Here is what it could mean for developers building on LLM APIs.
Source: TechCrunchRead article
A reported $446 million payout tied to Elon Musk's Twitter purchase is a reminder for developers to separate hype, platform risk, and real API costs.
Source: The VergeRead article
A Hacker News essay argues AI hype has made everything look like a scam. Here is what that skepticism means for developers building on LLM APIs.
Source: Hacker NewsRead article
Tech lobbyists reportedly cast US votes against AI and data centers as anti-Trump sentiment. Here is what that framing means for developers building on LLM APIs
Source: Ars TechnicaRead article
For projects already built on the official OpenAI or Anthropic SDKs, how do you connect to a unified gateway without changing business logic? This article provides a step-by-step migration checklist, verification methods, and common rollback plans.
Source: Admesh 技术团队Read article
Upstream rate limiting and failures are the norm, not the exception, for LLM applications. This article breaks down the correct handling for 429/5xx/timeout/401, when you can automatically switch channels, when you must never retry, and how to avoid double billing.
Source: Admesh 技术团队Read article
In the same product, using a flagship model for everything is usually the most expensive approach. This article presents a task-based tiering method for model selection: how to break down tasks, how to use an evaluation set to verify whether downgrading is safe, and how to switch models in the same codebase with a unified gateway.
Source: Admesh 技术团队Read article
Both Anthropic and OpenAI offer batch processing channels, trading a lower unit price for longer response times. This article provides an actionable decision framework: which tasks should go through batch, which must go real-time, and how to manage both types of traffic with the same gateway.
Source: Admesh 技术团队Read article
Prompt caching can reduce the input token cost of repeated prefixes by an order of magnitude. This article breaks down the differences between Anthropic's and OpenAI's cache implementations, which scenarios actually save money, and how to reuse the same caching strategy across multiple models with a unified gateway.
Source: Admesh 技术团队Read article
One OpenAI-compatible API, one Base URL and one key for the major models. Pay per token; new accounts get trial credit.